Decision models for robotics data curation
A lot of robot data curation is small multiple-choice calls. Does this report back up its verdict? Which slot does this note mean? Is the task finished in this picture? A decision model is built for exactly that. You hand it the question and the options, and it picks one and tells you how sure it is, in well under a second. We've been using Jev from TypeSafe for this. OpenAI opened its own, the Decision API, earlier this month. And this week Jev learned to look at pictures too. So we ran both through every test we have on our robot data, text and images, next to the big general models and our own harness.
Updated 16 October 2026. Jev can now look at pictures, so this version adds it to every image test, and every decision-model answer was asked again that day.
Setup
What we tested, and how
Everything here comes from real recordings of two robots. One is a two-arm robot restocking a shelf, mostly from our hard set, where most attempts go wrong on purpose. The other packs clothes into a bag. The text tests use what our pipeline actually produces: a vision model’s write-up of an episode, a curator’s notes, and the actions a video model detected. The image tests use the frames themselves. Every model got the same questions, the same options and the same answer keys.
Two versions of Jev are in the race. Jev 1.13 is TypeSafe’s current stable release. Jev 1.14 came out on 14 October as a preview. TypeSafe also calls its picture support a preview, not yet ready for production. We ran both versions everywhere. Where the text quotes one number for Jev, it’s 1.14.
One wrinkle. Jev takes a few worked examples with every question, and a lot of our curation leans on them. OpenAI’s Decision API has nowhere to put them. So we asked it two ways: with the examples pasted into the question, which is what Jev sees, and with just the question. The second one is called rules only in the charts.
Every decision-model answer in this version was asked on 16 October, with the same requests as before. Ask the same text question twice that day and OpenAI’s gives the same answer every time, Jev 99.5% of the time.
Since 7 October
What changed for OpenAI’s in nine days
We first ran OpenAI’s Decision API on 7 October. Nine days later we sent it exactly the same questions again. It had moved: better on some tests, worse on others.
- Better. It caught more of the reports whose counts don’t add up (13% then, 27% now), and found more of the matching notes in search (85% then, 88% now). Its score for keeping or removing whole recordings (F1, explained below) went from 0.63 to 0.69.
- Worse. It caught fewer of the contradictions in a report (25% then, 13% now), and called more of the standing boxes fallen (36% then, 43% now). The share of its answers that can go through without a person checking went from 66% to 63%.
Jev barely moved. Asked the same questions as in our first round, Jev 1.13 gave the same answer 99.7% of the time.
Speed and the routine stuff
Both are fast, and both get the routine reading right
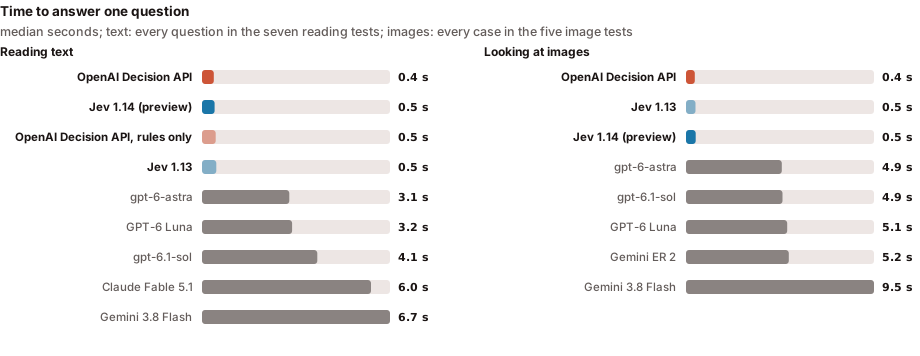
Both decision models answer a text question in about half a second (0.4 s for OpenAI’s, 0.5 s for Jev). The fastest general model we tried takes 3.1 s. Pictures are just as quick: 0.4 s for OpenAI’s and 0.5 s for Jev, against 4.9 s for the fastest vision model. That adds up when a dataset throws up thousands of these questions and someone is waiting on the answers.
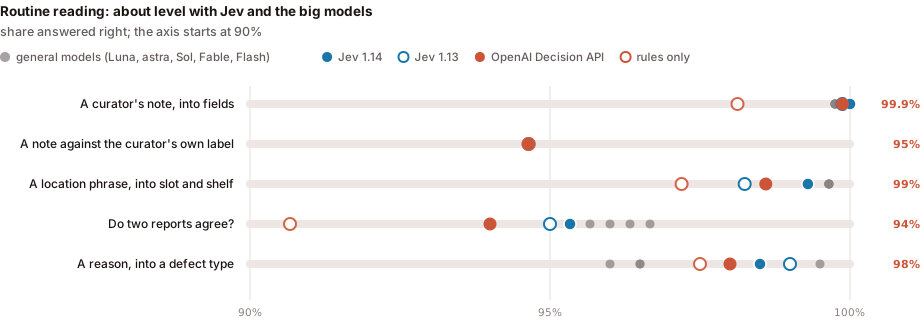
On the routine reading they’re both right nearly every time. Turning a curator’s note into fields, reading a phrase like “bottom right of the shelf”, checking whether two reports say the same thing, sorting a written reason into a defect type: OpenAI’s got 94% or better on each with the worked examples, about where Jev and the big models are.
Confidence
How much can you let through without checking?
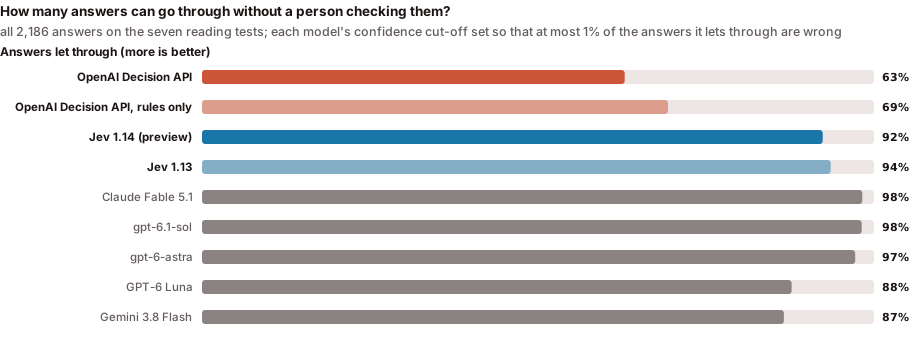
The way we’d actually use a decision model: take the confident answers and send the rest to a person. OpenAI’s guide says to set that cut-off from your own labelled examples, so we did that for every model and asked how many answers each one can let through while keeping mistakes at 1% or less.
Jev 1.14 lets through 92% of its answers, and 1.13 94%. OpenAI’s Decision API lets through 63%, or 69% without the worked examples. So on the same questions, a person would end up checking about 37% of OpenAI’s answers and 8% of Jev’s.
The big general models do even better here (98% for gpt-6.1-sol) because they’re right more often to begin with. They also take ten times as long per question. Claude Fable 5.1 scores as well, but it wrote the answer key for these tests, so take that with a pinch of salt.
Close calls
Where the two decision models split
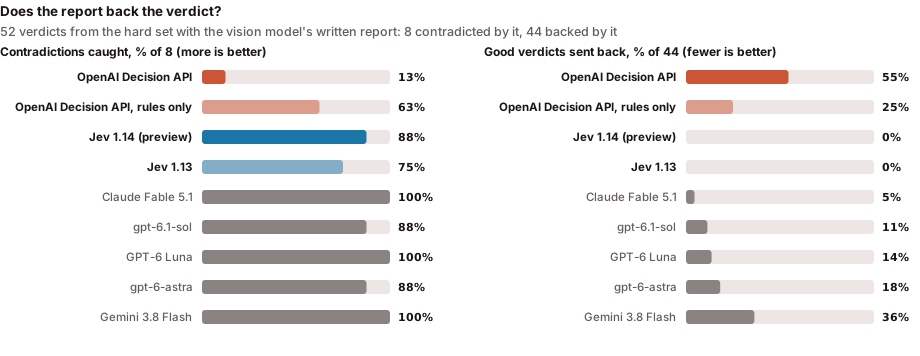
The tests that actually separate the models need a real call. Does a vision model’s own write-up back up its verdict? Does the count in a report add up? On these, OpenAI’s Decision API mostly said the text doesn’t settle it.
On the report check it caught 13% of the contradictions, and sent back 55% of the good verdicts for no reason. Jev 1.14 caught 88% and sent back none. Dropping the examples helped OpenAI’s a bit (63% caught, 25% sent back), but it still catches fewer contradictions than Jev or any of the general models.
The count check is just arithmetic, and one line of code gets every one right. With the examples, OpenAI’s sent back 91% of the counts that add up, and caught 27% of the ones that don’t. Jev 1.14 caught 93% and sent back none. That’s the one place the new Jev clearly moved: 1.13 still sent back 18% of the good counts.
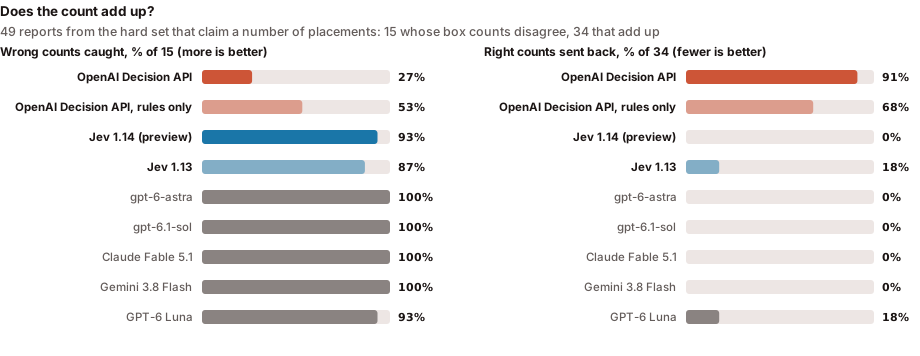
We don’t think it’s the model underneath. The Decision API runs on GPT-6 Luna, and plain Luna, asked through the normal API with the same examples, caught all of the contradictions and 93% of the bad counts. Something about how the Decision API reads long questions pushes it to “not enough to tell”. It said that on 71% of its answers across these two tests.
If a tool says “not enough to tell” on clear cases, a person ends up reading them anyway.
Head to head
When they disagree, Jev is usually right
Across all 2,186 answers, the two picked different options 6% of the time. When they did, Jev was right 92% of the time, OpenAI’s 7%, and neither 0.7%. Most of the splits are in search, the count check and the report check.
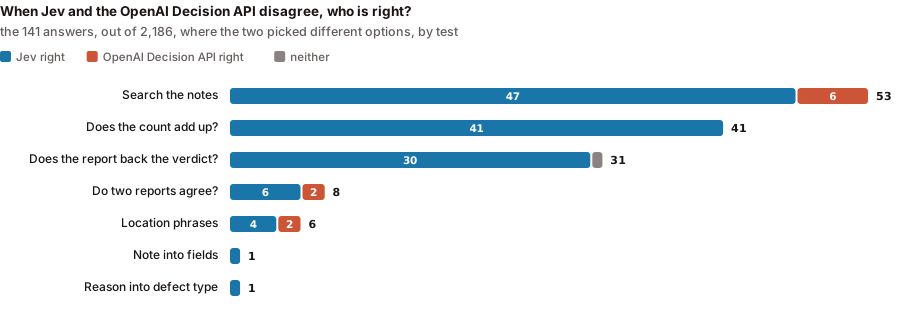
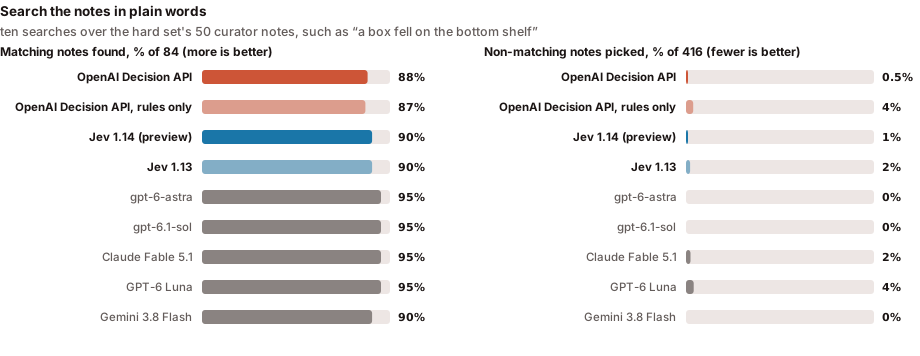
Search on its own: asked which notes match something like “a box fell on the bottom shelf”, OpenAI’s found 88% of the notes that do. Jev found 90%, gpt-6-astra 95%.
In the app
The job Jev actually does for us
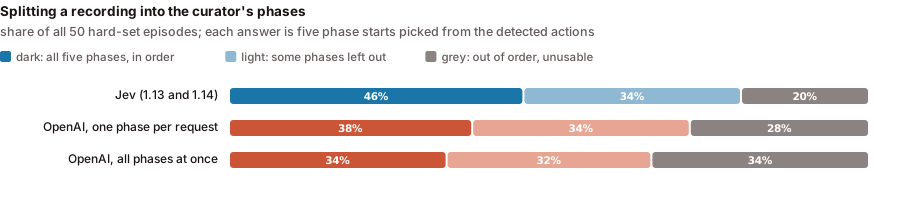
In our app, Jev has one real job on robot recordings. A video model lists every action it sees in an episode (reach, grasp, lift, place), and Jev groups those into the curator’s phases: first small box, second large box, third large box, last small box, back home. For each phase it picks the action where that phase starts.
We gave OpenAI’s Decision API the same requests Jev got for all 50 hard-set episodes. Jev answers all five phases in one go. OpenAI’s guide says questions that depend on an earlier answer should go in separate requests, so we asked it both ways: all at once, and one phase per request with the earlier answers passed along.
Jev came back with all five phases in order on 46% of the episodes, the same with both versions. OpenAI’s managed 38% one phase at a time and 34% all at once. An answer with the phases out of order is no use to anyone, and OpenAI’s gave one on 28% and 34% of the episodes, against Jev’s 20%.
The curator timed one episode by hand, ep001. There OpenAI’s boundaries were closer: 1.25 seconds off on average one phase at a time, against Jev’s 1.75. One episode isn’t much to go on, though.
Images
Both can look at pictures now. Neither can see a fallen box
Until this week only OpenAI’s Decision API took images. Now Jev does too, so we ran both versions of Jev through every image test, next to OpenAI’s, the vision models and the Qualia harness.
Start with an easy question: from the first and last frame, is the task finished? Jev 1.14 caught 86% of the episodes where the robot didn’t finish, and OpenAI’s 81%. Both called 7% of the finished ones unfinished. The vision models caught 90%, about the same, and took ten times as long.
How you hand over the pictures matters a lot. Give the decision models 16 frames from across the episode, one picture each, and they get better. Jev 1.13 then caught 95% of the unfinished episodes and OpenAI’s 95%. Neither flagged a single finished one. That’s close to the harness on this question, from a model that answers in a second.
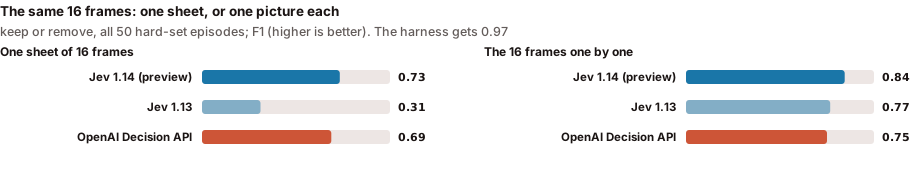
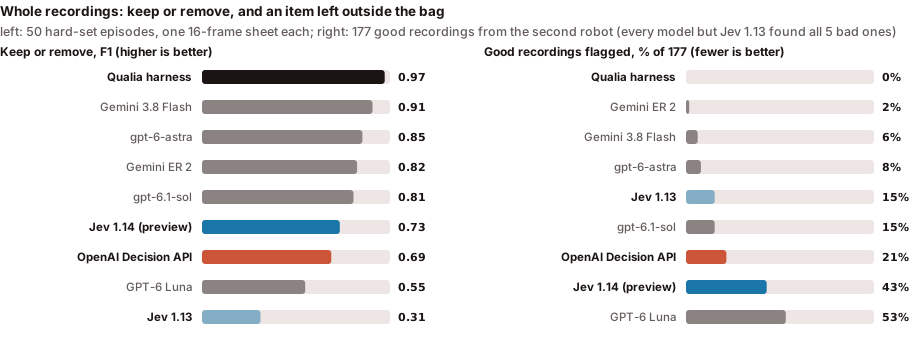
The same goes for whole recordings. Asked to keep or remove an episode from one sheet of 16 frames, Jev 1.14 got an F1 of 0.73 and OpenAI’s 0.69. (F1 balances the bad episodes caught against the good ones thrown out; 1 is perfect.) Given the same 16 frames one by one, Jev 1.14 reached 0.84 and OpenAI’s 0.75. For comparison, gpt-6-astra on the sheet gets 0.75–0.81, and the harness 0.97. Part of the gain is simply size: one picture per frame is much bigger than a frame squeezed onto a sheet.
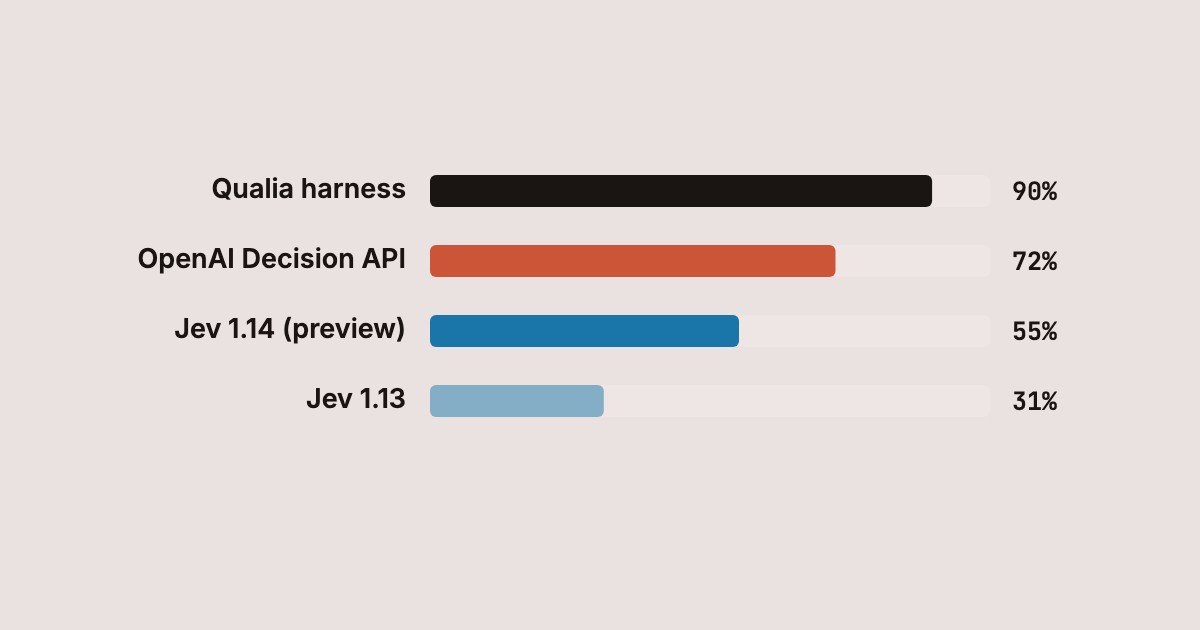
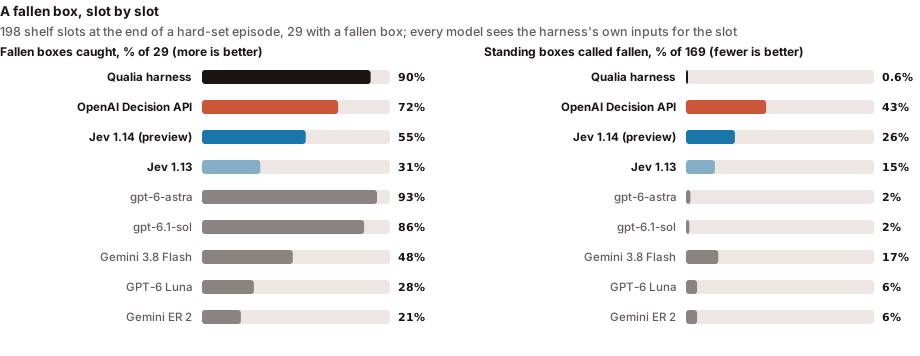
The hardest thing we check is a fallen box. On this shelf a fallen box can look a lot like a standing one, even to a person. The hard set has 198 slots we have answers for, and 15% of them hold a fallen box. The Qualia harness caught 90% of the fallen boxes and called 0.6% of the standing ones fallen.
Given exactly what the harness sees for each slot, OpenAI’s caught 72% but called 43% of the standing boxes fallen. Jev 1.14 caught 55% and called 26% fallen; 1.13 caught 31% and called 15% fallen. Someone would have to check every one of those false alarms. Put another way: when OpenAI’s says a box fell, it’s right 23% of the time, and Jev 1.14 27%. When the Qualia harness says so, it’s right 96% of the time. The best single models on the same inputs were gpt-6-astra (93% caught, 2% false alarms) and gpt-6.1-sol (86%, 2%). Those inputs do a lot of the work. They’re the curator’s examples, reference pictures of the slot and the close-up, which the harness puts together for every slot. Give gpt-6.1-sol just the rule and it catches 38% and calls 22% of the standing boxes fallen.
A cut-off doesn’t rescue it. Both decision models give a probability for every answer, so you could raise the bar for “fallen”. But their confidence doesn’t sort fallen boxes from standing ones well: about 0.67–0.71 on a scale where a coin toss is 0.5 and perfect is 1, against 0.99–1.00 for gpt-6-astra and gpt-6.1-sol. Allowed no more false alarms than gpt-6-astra’s 4, the best cut-off catches 1 of the 29 fallen boxes for Jev 1.14 and 6 for OpenAI’s.
On the easy question it’s a different story. On whether the task is finished, both decision models sort the cases about as well as the vision models do (0.93–0.96, against 0.91–0.98).
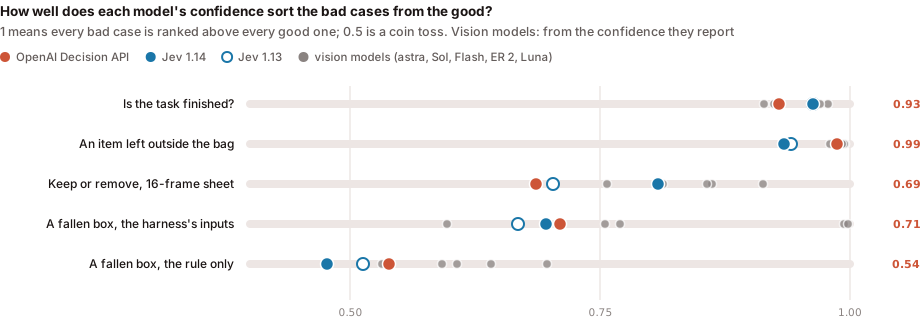
We also tried giving Jev the pictures the way TypeSafe designs for. Jev can take example pictures inside each option, so we put the fallen examples under “fallen” and the standing ones under “standing”. That made its confidence a little more useful, but its answers didn’t improve: Jev 1.14 caught 41% and called 21% fallen. Sending the example pictures at full size instead of shrunk to fit didn’t help either.
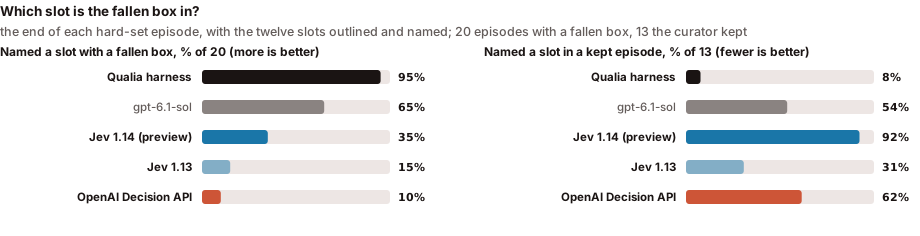
Then the next question a reviewer asks: which slot is it in? We showed each model the end of the episode, once plain and once with the twelve slots outlined and named. On the 20 episodes with a fallen box, the harness named a right slot in 95%. gpt-6.1-sol managed 65%, Jev 1.14 35%, Jev 1.13 15% and OpenAI’s 10%. Jev 1.14 can also draw a box around what you ask for. Asked to box the fallen box, it landed inside a fallen box’s slot in 3 of 20 episodes.
On the second robot, every model found the items left outside the bag, except Jev 1.13, which missed one. The difference is in the false alarms: Jev 1.13 flagged 15% of the good recordings, OpenAI’s 21%, Jev 1.14 43%. The harness flagged none.
Jev is steady on pictures: asked twice, it gave the same answer 93%–98% of the time, depending on the test. OpenAI’s changed between our two rounds, nine days apart, on the same requests: it gave a different answer on 30% of the keep-or-remove sheets and 16% of the fallen-box slots.
All results
The full table
Where a cell has two numbers, the first is the share it caught and the second the share it flagged by mistake, each out of the count in the row’s note. Everything is on the shelf robot’s hard set, except the location phrases, which use both shelf sets, and the bag test, which is the second robot. The Jev columns show the same version on text and images.
| The test | OpenAI Decision API | OpenAI Decision API, rules only | Jev 1.14 (preview) | Jev 1.13 | GPT-6 Luna | gpt-6-astra | gpt-6.1-sol | Claude Fable 5.1 | Gemini 3.8 Flash | Gemini ER 2 | Qualia harness |
|---|---|---|---|---|---|---|---|---|---|---|---|
| Reading text | |||||||||||
| Does the report back the verdict? (contradictions caught (of 8) · good verdicts sent back (of 44)) | 13% · 55% | 63% · 25% | 88% · 0% | 75% · 0% | 100% · 14% | 88% · 18% | 88% · 11% | 100% · 5% | 100% · 36% | — | — |
| Does the count add up? (wrong counts caught (of 15) · right counts sent back (of 34)) | 27% · 91% | 53% · 68% | 93% · 0% | 87% · 18% | 93% · 18% | 100% · 0% | 100% · 0% | 100% · 0% | 100% · 0% | — | — |
| Search the notes (matching notes found (of 84) · non-matching picked (of 416)) | 88% · 0.5% | 87% · 4% | 90% · 1% | 90% · 2% | 95% · 4% | 95% · 0% | 95% · 0% | 95% · 2% | 90% · 0% | — | — |
| A curator’s note, into fields (share right) | 99.9% | 98% | 100% | 99.9% | 99.8% | 99.8% | 99.8% | 99.8% | 99.8% | — | — |
| A note against the curator’s own label (share right) | 95% | 95% | 95% | 95% | 95% | 95% | 95% | 95% | 95% | — | — |
| A location phrase, into slot and shelf (share right) | 99% | 97% | 99.3% | 98% | 99% | 99.6% | 99.6% | 99.6% | 99.6% | — | — |
| Do two reports agree? (share right) | 94% | 91% | 95% | 95% | 95% | 96% | 96% | 96% | 97% | — | — |
| A reason, into a defect type (share right) | 98% | 98% | 99% | 99% | 98% | 97% | 97% | 99.5% | 96% | — | — |
| Median seconds per question | 0.4 s | 0.5 s | 0.5 s | 0.5 s | 3.2 s | 3.1 s | 4.1 s | 6.0 s | 6.7 s | — | — |
| Looking at images | |||||||||||
| A fallen box, harness inputs (caught (of 29) · standing called fallen (of 169)) | 72% · 43% | — | 55% · 26% | 31% · 15% | 28% · 6% | 93% · 2% | 86% · 2% | — | 48% · 17% | 21% · 6% | 90% · 0.6% |
| A fallen box, rule only (caught (of 29) · standing called fallen (of 169)) | 76% · 82% | — | 76% · 71% | 62% · 54% | 62% · 50% | 45% · 22% | 38% · 22% | — | 38% · 28% | 52% · 56% | — |
| Is the task finished? (first and last frame; unfinished caught (of 21) · finished called unfinished (of 29)) | 81% · 7% | — | 86% · 7% | 76% · 7% | 90% · 7% | 90% · 10% | 90% · 10% | — | 90% · 10% | 90% · 7% | 100% · 10% |
| Keep or remove the recording (one sheet of 16 frames; F1) | 0.69 | — | 0.73 | 0.31 | 0.55 | 0.85 | 0.81 | — | 0.91 | 0.82 | 0.97 |
| An item left outside the bag (second robot; caught (of 5) · good flagged (of 177)) | 100% · 21% | — | 100% · 43% | 80% · 15% | 100% · 53% | 100% · 8% | 100% · 15% | — | 100% · 6% | 100% · 2% | 100% · 0% |
| Median seconds per case | 0.4 s | — | 0.5 s | 0.5 s | 5.1 s | 4.9 s | 4.9 s | — | 9.5 s | 5.2 s | — |
Takeaway
So which would we use?
- A decision model, for the small text questions. There are thousands of them in a dataset. It’s ten times faster than a general model, and when it says it’s sure, you can mostly take its word for it.
- Jev, for now. It catches more of the close calls, gets the phases in order more often, and lets far more answers through without a person checking them. OpenAI’s is just as fast and just as good on the routine reading.
- A decision model for easy pictures, if you hand them over one frame at a time. Both can now say whether a task got finished, in a second, about as well as a vision model.
- Not a decision model, for a fallen box. Neither can reliably tell a fallen box from a standing one, or say which slot it’s in. On that, no single model matched the harness, and the decision models were well behind the best vision models.
- Code, for counting. One line gets it right every time.
If we could ask OpenAI for one thing, it would be a proper place for worked examples. That’s how what the curator knows ends up in every question. Jev already takes example pictures inside its options. On a fallen box that hasn’t paid off yet, but it’s the right place to put them.
How we ran it. Every decision-model answer is from 16 October 2026: Jev 1.13 and Jev 1.14 from TypeSafe, and OpenAI’s Decision API on the model OpenAI runs it on (GPT-6 Luna), with the same requests we sent on 7 October. The general models’ answers are from 6 and 7 October, and gpt-6-astra’s fallen-box slots from 12 October. The text tests come from our earlier decision-model study: questions written on 30 September from real curation text, an answer key written before any model ran (by Claude Fable 5.1), and nine disputed cases settled by a person. The phase test reuses the exact requests Jev got on 30 September; the curator’s ep001 phases are one development example. The image tests are scored against the curator’s labels. Requests follow each provider’s guide. OpenAI’s: text as the input (images as inline base64), each question as plain-text instructions with a list of options; the guide has no field for worked examples, and for the phase test we also asked one phase per request, as it advises for dependent questions. TypeSafe’s: images as attached assets, which its preview accepts between 280 and 1,568 pixels a side, so the two widest pictures (the harness’s example pictures and the 16-frame sheet) were shrunk and padded to fit. The one-frame-at-a-time, examples-in-the-options and full-size variants were each asked once. The slot-naming test shows every model the same two pictures of the end frame. Confidence cut-offs were set per model from the same labelled answers they are scored on, which flatters every model equally. An answer that isn’t one of the options counts as wrong, and “not enough to tell” counts as sending the case back. The harness’s fallen-box figure is its best of three runs of the check as updated on 7 October; the other two caught 83%–90% with 1%–2% false alarms.